Today
Introducing the first audio-native decision model
The intelligence of millions of human listeners, built into one model. Turn questions about audio into fast, structured, probabilistic judgments, without relying on transcripts or building separate models for every task.
Customer Calls
We engage customers to learn their challenges and make AI feel more human.
Pick OneWhat emotion is the customer exhibiting?
Pick OneWhat language is spoken?
Yes/NoDoes the reply address what the caller asked?
Pick OneHow many people are speaking?
ScaleHow intrusive is the background noise?
Add questionYou can add or change a question any time.
Trusted by AI leaders
Built on Proven Science
- Leading AI labs
- 5 of 7
- Languages supported
- 50+
- Speech samples
- 100M+
- Emotion science research
- 10+ years
There is more to voice
than words.
A task can succeed while the conversation fails. Humans judge voice AI on timing, tone, emotional expression, interruption, accent, context, and adaptation. Hume measures all of it.
From complex pipelines
to one model
Hume’s audio-native model integrates speech, sound, and context to answer audio questions. It replaces complex models with structured answers in one API call.
With Hume
One model, all answers structured
and in context
One evaluation platform
for models and agents
Select the right model, define use-case-specific quality, validate realistic interactions with automated and human evaluation, and turn findings into focused improvements.
Voice Model evaluation workflow: start, define quality for tone, timing and turn-taking, then automated stress-test scenarios (passed, 0.91) and trained human raters (4.7 average), then compare checkpoints (+0.12 overall, -0.03 clarity).
Explore model developmentChoose the right model for your agent, simulate real customer calls, validate with trained raters, and ship focused fixes with confidence.
Deploy Agent transcript: the caller urgently asks about a late order; intent detected as order status; the voice agent replies after a 910 millisecond gap that the order ships Friday; urgency not acknowledged; automated score 84%, human score 79%; focused improvement: acknowledge first.
Explore voice agentsSee how leading voice models
perform in the real world
VoiceEQ assesses voice systems in real conditions, merging objective metrics with human insights to highlight strengths and tradeoffs.
 gemini-3.1-flash-liveGoogle3.76
 gpt-realtime-2OpenAI3.74
 agentElevenLabs3.45
 grok-voice-2.0xAI3.41
 qwen3-omni-30b-a3bQwen3.19
Voice-native infrastructure
for better evaluation and training
User Testing API
Prepare audio for training
Transform unstructured audio into searchable, expression-rich inputs.
Expression APIs
Measure what transcripts miss
Measure vocal expression, timing, and conversational dynamics.
Human Feedback API
Evaluating human judgment
Conduct evaluations with trained raters to assess people's experiences.
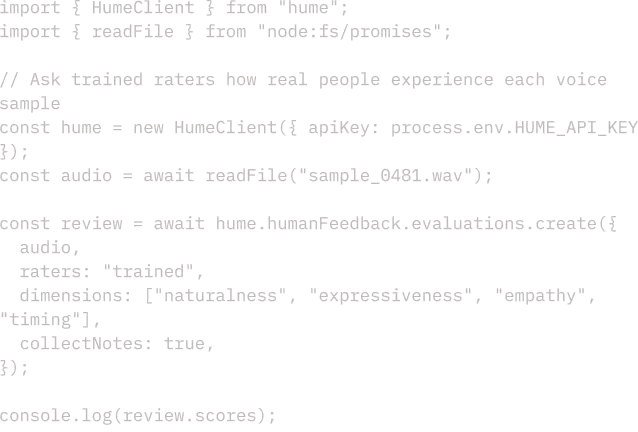
Access Hume's research systems to develop voice models. Use APIs to enrich audio, measure expression, and incorporate judgment.
Explore evaluation

